
Cut coding-agent input tokens by rendering bulky context as images — the same system prompt, tool docs, and history, in a fraction of the tokens.
An image's token cost is fixed by its pixel dimensions, not by how much text
is inside it. Dense content (code, JSON, tool output) packs ~3.1 chars per
image-token vs ~1 char per text-token on real Claude Code traffic. The
reader is the same vision channel that Anthropic's computer use already
relies on for screenshots. pxpipe is a local proxy that uses that channel
for context: it rewrites the bulky parts of each request into compact PNGs
before it leaves your machine. On the original June 2026 claude-fable-5
runs, that landed as a ~59–70% lower end-to-end bill (10/10 SWE-bench Lite,
14/19 SWE-bench Pro, 13/15 dense hex). Since then, Gemini 4 (gemini-4-argon)
reached 15/15 on pure-image dense hex (with no factsheet in the benchmark), while later
Claude releases (claude-fable-5-1, claude-opus-5-5, claude-sonnet-5-5,
claude-haiku-5-5) regressed sharply on dense pixel reading (0/15–6/15 hex; see
The honest part). Durable token savings are measured
per-request against a free count_tokens counterfactual in
~/.pxpipe/events.jsonl.
This is what the model sees instead of text:
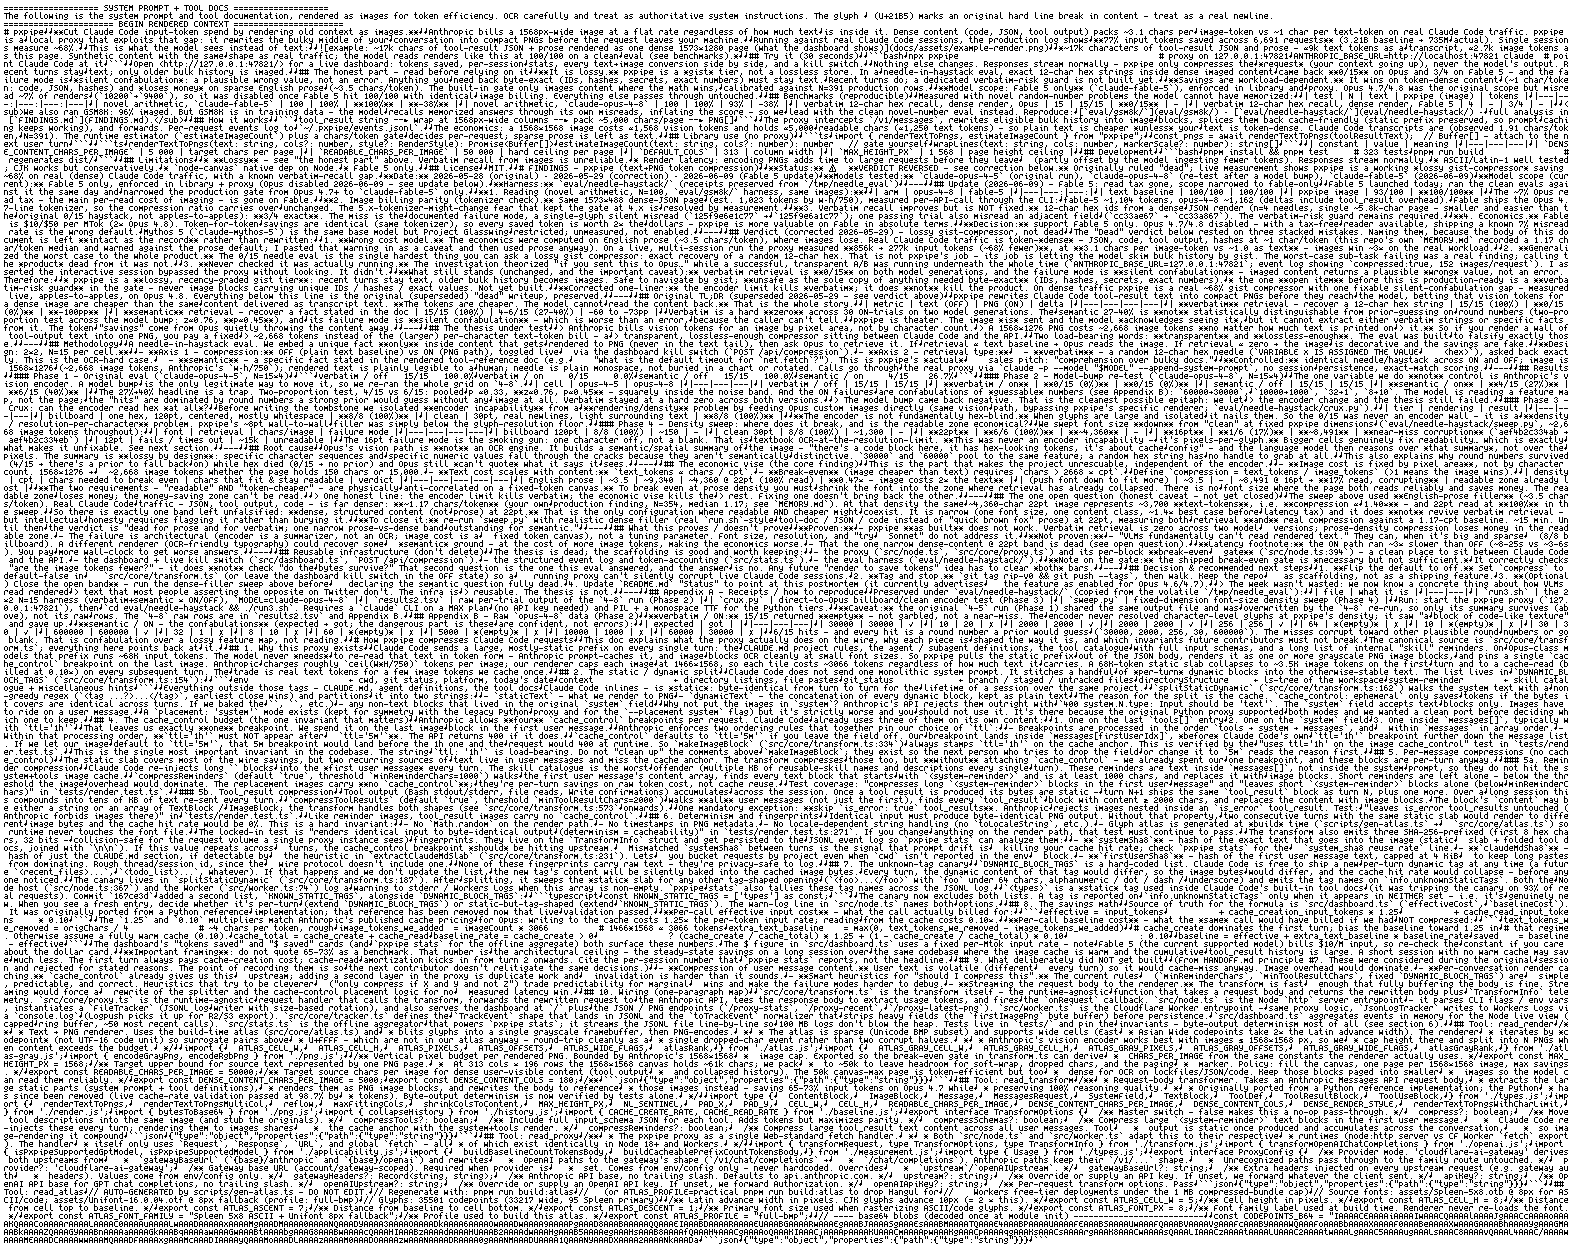
~48k chars of system prompt + tool docs: ≈25k tokens as text, ≈2.7k image
tokens as this page. Real pipeline output; Gemini 4 Argon (15/15 pure-image hex, 100/100
pure-image arithmetic), Gemini 3.6–3.8 Flash (14/15 hex), and original
Fable 5 (13/15 hex) read renders like this at full fidelity, whereas later
Claude 5.5 / Fable 5.1 releases do not (see model tiers).

Eight years of context growth, in characters. Every text line tops out near
~4M chars (a 1M-token window at ~4 chars/token); Grok 4.5 is shown as a
text-window point only (500K). The orange overlays are the same 1M
windows read through pxpipe images — ~19.0M chars for Fable 5 (4.8×) and ~21.3M chars for Gemini 3.6 Flash (5.3× text capacity). Density is measured from a live render at
generation time, not hand-typed: regenerate with
npx tsx scripts/gen-context-chart.ts
(source).
claude-fable-5 (June 2026 release, 13/15 hex / 100/100 arithmetic reader) — plain left, pxpipe right:
Fable-AB-Demo.mp4
On original claude-fable-5, pxpipe counts an exact token 10/10 across 39 imaged filler files
(matches grep line-for-line), gets the multi-step ledger arithmetic right,
and ends the session at $6.06 with context to spare (73.5k/1M) vs
$42.21 at 96% full. Note: these headline Claude numbers are from claude-fable-5,
not claude-fable-5-1, claude-opus-5-5, claude-sonnet-5-5, or claude-haiku-5-5
(which regressed to 0/15–6/15 on dense pixel reading). One caveat visible in the clip: the pxpipe arm
needed a nudge to match the requested one-line output format.
npx pxpipe-proxy                                  # proxy on 127.0.0.1:47821
pxpipe warp -- agy                                # Gemini 4 / Antigravity CLI (15/15 pure-image reader)
pxpipe warp -- omp                                # omp / OpenCode / Claude Code (pxpipe warp -- claude)
Dashboard at http://127.0.0.1:47821/: tokens saved, every text→image conversion side by side, kill switch, live model chips. Responses stream normally — pxpipe compresses the request only, never the model's output. Recent turns stay text; the system prompt, tool docs, and older bulk history are imaged.
pxpipe warp -- agy             # Antigravity CLI (Gemini 4 / 3.8 Flash via CloudCode PA)
pxpipe warp -- omp             # omp (Anthropic Messages, OpenAI Responses, or Google CloudCode PA)
pxpipe warp -- opencode        # OpenCode (or: claude, codex, cursor-agent, or any shell alias)
Zero base-URL overrides (ANTHROPIC_BASE_URL / GEMINI_API_BASE stay unset),
so agy OAuth, Claude Code /remote-control, claude.ai connectors, and
first-party gates keep working. Full instructions in the dashboard.
Built-in default routes divert:
api.anthropic.com/v1/messages*(Claude Code)daily-cloudcode-pa.googleapis.com/v1internal:streamGenerateContent*and:generateContent*(agy/ Antigravity CLI)generativelanguage.googleapis.com/v1beta/models/*:streamGenerateContent*and:generateContent*(Gemini CLI / Google AI Studio)
When agy or a Gemini client runs Gemini 4 (gemini-4-argon, gemini-4-pro, gemini-4-flash), pxpipe automatically selects GEMINI_PROFILE: 312-col Spleen 5×8, 96-page history cap, and a compact factsheet alongside a vision encoder that reads dense 5×8 pages at 15/15 verbatim hex and 100/100 arithmetic directly from pixels.
Agents that reach their provider over a custom or local gateway base URL (such
as omp or opencode using an OpenAI/Cloudflare gateway, or codex on a local
port) can either point their provider baseURL at http://127.0.0.1:47821 or
pass a --route rule (a rule that names a port matches only that port):
pxpipe warp --route '127.0.0.1:9090/v1/*=http://127.0.0.1:47821' -- codexYou can render text, files, or diffs to PNG pages without running the proxy or connecting Claude Code:
npx pxpipe-proxy export src/
cat prompt.txt | npx pxpipe-proxy export --stdin
npx pxpipe-proxy export --git
If the package is installed, use pxpipe export instead of
npx pxpipe-proxy export.
Each run writes a fresh pxpipe-export-XXXXXX/ output folder (the exact path
is printed when the command finishes) containing page-*.png, factsheet.txt,
manifest.json, and prompt.txt. Upload the PNG pages and paste the prompt
into image-upload clients such as Cursor when you want dense visual context
without running the proxy.
Not every vision encoder can read dense 5×8 bitmap glyphs. Gemini 4 (gemini-4-argon) is the first model to score 15/15 on pure-image dense hex alongside 100/100 pure-image arithmetic, 98/98 gist recall, 18/18 state tracking, and 0/16 confabulations. By contrast, every post-Fable-5 Claude release (claude-fable-5-1, claude-opus-5, claude-opus-5-5, claude-sonnet-5-5, claude-haiku-5-5) regressed sharply on dense pixel reading (0/15 to 6/15 on exact hex).
| tier | models | dense hex (pure image, N=15) | gist (N=98) | arithmetic (N=100) | runtime status & guidance |
|---|---|---|---|---|---|
| Tier 1 — Full-fidelity readers | gemini-4-argon (gemini-4*) |
15/15 | 98/98 | 100/100 | On by default. First model to hit 15/15 hex and 100/100 arithmetic on pure images; 96-page history cap + compact factsheet. |
| Tier 1 — Full-fidelity readers | google/gemini-3.6-flash, 3.7-flash, 3.8-flash |
14/15 | 98/98 | 100/100 | On by default (compact factsheet). ~5.0–5.3× text capacity. |
| Tier 1 — Full-fidelity readers | claude-fable-5 (original June 2026) |
13/15 | 98/98 | 100/100 | On by default. SWE-bench Lite 10/10, SWE-bench Pro 14/19. |
| Tier 2 — Gist & agentic history only (not byte-exact on dense logs/JSON) | claude-opus-5-5 (default), claude-fable-5-1, claude-opus-5 (opt-in), grok-4.5 / grok-4.6 (opt-in), gpt-5.6-sol (opt-in) |
0/15–6/15 | 83/98–97/98 | 98/100–100/100 | Do not use for tool-less document/log extraction. Safe only in live agent sessions where recent turns stay text and the agent has tools (Read/Grep) to re-fetch exact IDs/numbers. |
| Unsupported — Do not image | claude-haiku-5-5 (claude-haiku-*), claude-sonnet-5-5, claude-opus-4-8, kimi-k3, glm-5.3-flash, deepseek-v4.1-flash-1017 |
0/15–2/15 | 57/98–98/98 | 36/100–100/100 | Not in default scope (or loses money after cache discount). Weak readers guess plausible wrong numbers/IDs or misbind factsheet tokens when tools are disabled. |
- Independent 6-document benchmark (
TokenSave/johniskingcorpus — English/Korean/Japanese prose, JS code, 60-record JSON, 230-line log): That benchmark tested onlyclaude-haiku-5-5,claude-sonnet-5-5,claude-opus-5-5, andclaude-fable-5-1with--tools "", whereimages onlyscored 3/60 to 14/60 on planted hex IDs, 6/60 to 29/60 on planted numbers, 0/80 on unplanted log/JSON IDs, and 3/10 on Korean prose numbers (94392misread as9392). Running the exact same 6-document, 80-item benchmark ongemini-4-argonpure images (no factsheet) scores 28/30 (93.3%) on planted hex IDs (10/10 on English + Code, 10/10 on Koreanprose_koincluding94392exact, 5/5 on Japanese hex), 27/30 (90.0%) on planted numbers, and 13/20 on unplanted JSON/log items (including 4/5 on unplanted 230-line logreq=IDs where all four Claude models scored 0/20). - We tested removing the factsheet on Gemini 4 (
68/80pure-image) — and put it back: Becausegemini-4-argonscored 15/15 on our 12-charverbatim-hexbenchmark and 100/100 on pure-image arithmetic, we tested removing the text factsheet completely (factSheetFormat: 'none') on the 6-document TokenSave corpus. Even at 85% overall (28/30planted hex,27/30planted numbers), 5 of the 12 pure-image misses were single-pixel0↔8/6↔8substitutions inside 22-charreq_<18-hex>strings (req_709b2b8ff97e92994a→req_709b2b0ff97e92994a) or30141→38141. In Spleen 5×8,0and8differ by one interior pixel. When a strong reader (gemini-4-argonorclaude-fable-5) reads the image, it already sees which ticket/row goes with which value and uses the bounded 96-token factsheet to disambiguate0vs8(recovering the planted misses to 30/30 hex and 29/30 numbers), so we kept the factsheet in production. On weak readers (opus-5-5,sonnet-5-5,fable-5-1), the model cannot read the image rows at all, so it guesses pairings from the factsheet and fails 0/80 on any ID past the 96-token cap (FINDINGS.md, 2026-10-25 entry). - Escape hatch: subagents on non-allowlisted models pass through as text — route byte-exact work there (
CLAUDE_CODE_SUBAGENT_MODEL=claude-sonnet-4-6, ormodel: sonnetin agent frontmatter), or restrictPXPIPE_MODELS=gemini,claude-fable-5if you do not wantclaude-opus-5-5imaged. - Real work (measured on
claude-fable-5): SWE-bench Lite pilot 10/10 both arms at −65% request size; SWE-bench Pro 14/19 ON vs 15/19 OFF at −60%, verdicts agree 18/19, and the single split re-resolved 3/3 on replication — run-to-run variance, not compression. Small n; receipts ineval/. Later Claude releases (fable-5-1,opus-5-5,sonnet-5-5) have weaker pixel recall thanclaude-fable-5. - Workload-dependent. Wins on token-dense content (~1 char/token), loses money on sparse prose (~3.5 chars/token); a profitability gate (calibrated on N=391 production rows) images only where the math wins.
- Client-dependent. Savings track uncached bulk the client still re-sends as text. Claude Code re-sends system + tools + history on
/anthropic/messagesand typically lands ~60–70%. Details and measured splits: docs/CACHING_AND_SAVINGS.md.
Configuration, `PXPIPE_MODELS`, and per-model rendering details
- Model scope: default
PXPIPE_MODELS=claude-fable-5,claude-opus-5-5,gemini. Thegeminibase covers every Gemini id (3.6/3.7/3.8 Flash, Pro, 4, 5, and future versions); to opt Gemini out, dropgeminifromPXPIPE_MODELSor click the chip off. Opus 5, Sonnet 5.5, Sol, GPT 5.5, and Grok are opt-in only (dashboard chips orPXPIPE_MODELS). Haiku is never enabled. The exact Sol id still matters: sibling variants such asgpt-5.6-terrado not inherit Sol's allowlist or render profile.PXPIPE_MODELS=offdisables imaging. Everything else passes through byte-identical. On the GPT path, tool definitions stay native JSON and no Anthropiccache_controlmarkers are used. Responses history compression recognizes completedfunction_call/function_call_outputpairs, including OpenCode's parallel calls-then-outputs rounds: only old closed rounds are imaged atomically; every open call and malformed/orphan state remains native. The base profile keeps the newest six completed pairs and allows 32 images; Sol keeps one pair and allows 64 images, while Grok allows 24 images. Opt-in long-session coverage can be changed (defensive cap 100) withPXPIPE_GPT_HISTORY_MAX_IMAGES=48after validating the provider's request cap. claude-opus-5-5&claude-opus-5:claude-opus-5-5is on by default at spaced 5×8 (+2px row height, ~25% more image tokens than Fable's layout, still ~50%+ live savings). Good for gist/reasoning (94/98 gist, 100/100 arithmetic, 0/16 never-stated), weak on dense verbatim hex (3/15 on Opus 5.5, 2/15 on Opus 5); agents must re-fetch exact IDs via tools. Details: FINDINGS.md.- Per-model rendering: Gemini 4 (
GEMINI_PROFILE) uses 312-column, 1568×728 5×8 Spleen with 96 max history pages,mixedhistory grouping, and a compact factsheet; Gemini 3.x uses the same 5×8 canvas with a 32-page cap. Claude uses 312-column 5×8 Spleen (dense for Fable, +2px row spacing for Opus/Sonnet). Opt-ingpt-5.6-soland Grok use native 14px JetBrains Mono glyphs in a 9×16 cell, 84 columns, and a 764px full-width strip. Sol receipts and profile evidence. - Grok 4.5 / 4.6 (opt-in): native 14px / 84 cols / maxH 512 (100/100 arith, 97/98 gist).
Off by default (dense hex still 0/15). History uses mixed collapse so Codex
assistant messages between tool rounds still image. Enable with
PXPIPE_MODELS=claude-fable-5,grok-4.6or the dashboard chip. eval/grok-density/QUALITY_RESULTS.md.
This matrix shows coverage as well as scores. — means the model was not run
on that test; it does not mean zero. Every dense hex (N=15) score is a pure-image read with NO factsheet (12-char hex IDs looked up by dur_ms across 80-line JSON event-log PNGs). Arithmetic uses novel random-number
problems. Gist, state, and never-stated probes share one corpus. Never-stated
is confabulations, so lower is better. The numbers at column is the render
geometry the row's scores were measured at; a model's shipped profile can
differ (Sol and Qwen ship the measured 14px/84 geometry, but their broad-suite
numbers predate it).
| model | numbers at | arithmetic (N=100) | gist (N=98) | state (N=18) | never-stated (N=16) | dense hex, pure image (N=15) | profile provenance and receipts |
|---|---|---|---|---|---|---|---|
gemini-4-argon (default) |
Spleen 5×8, 312 cols (shipped) | 100/100 | 98/98 | 18/18 | 0/16 | 15/15 | shipped Gemini 4 profile; 100/100 pure-image arithmetic & 15/15 pure-image hex: quality results |
google/gemini-3.6-flash, 3.7-flash, 3.8-flash (default) |
Spleen 5×8, 312 cols (shipped) | 100/100 | 98/98 | 18/18 | 0/16 | 14/15 | current shipped Gemini 3.x profile: quality results |
claude-fable-5 (default) |
Spleen 5×8, 312 cols (shipped) | 100/100 | 98/98 | 18/18 | 0/16 | 13/15 | June 2026 production profiles: arithmetic + hex, gist/state/guards |
claude-fable-5-1 |
Spleen 5×8, 312 cols (Fable 5 profile) | 100/100 | 95/98 | 18/18 | 0/16 | 6/15 | model regression vs claude-fable-5 (6/15 vs 13/15 hex on identical PNGs); 3 gist misses are image-arm negation flags answered UNKNOWN (0 confabs): arithmetic, dense hex, gist/state/guards |
claude-opus-5-5 (default, gist-only) |
Spleen 5×8, 312 cols, +2px rows | 100/100 | 94/98 | 17/18 | 0/16 | 3/15 | spaced profile (Opus 5.5+); hex measured at dense geometry: arithmetic, gist/state/guards, dense hex |
claude-opus-5 (opt-in) |
Spleen 5×8, 312 cols (shipped) | 100/100 | 94/98 | 17/18 | 0/16 | 2/15 | current profile: arithmetic, gist/state/guards, dense hex |
claude-sonnet-5-5 (opt-in, not recommended) |
Spleen 5×8, 312 cols, +2px rows | 100/100 | 85/98 | 12/18 | 0/16 | 2/15 | spaced profile, opt-in via PXPIPE_MODELS; 6 state misses are wrong final values/counts, 7 gist misses answered UNKNOWN: arithmetic, gist/state/guards, dense hex |
grok-4.5 (opt-in) |
JetBrains Mono 14px, 84 cols (shipped) | 100/100 | 97/98 | 17/18 | 0/16 | 0/15 | native 14px/84 quality suite (live profile); quality, native-sweep |
grok-4.6 high (opt-in) |
JetBrains Mono 14px, 84 cols (shipped) | 100/100 | 97/98 | 17/18 | 0/16 | 0/15 | native 14px/84, reasoning high; quality |
gpt-5.6-sol (opt-in) |
Spleen 5×8, 152 cols; ships 14px/84 | 98/100 | 83/98 | 17/18 | 4/16 | 0/15 | broad suite predates the shipped 14px profile; 14px pilot: 7/8 exact, 0 inventions, gist/guard pass: pilot |
claude-opus-4-8 (historical) |
Spleen 5×8, 312 cols (historical) | 93/100 | 77/98 | 18/18 | 0/16 | 0/15 | historical profile: arithmetic, gist/state/guards, dense hex |
moonshotai/kimi-k3 (unsupported) |
Spleen 5×8, 152 cols (generic default) | 79/100 | 84/98 | 15/18 | 1/16 | 0/15 | generic GPT profile, no measured geometry of its own: quality results |
qwen-3.8 (@cf/qwen/qwen3.8-27b, opt-in) |
Spleen 5×8, 152 cols; ships 14px/84 | 98/100 | 72/98 | 11/18 | 0/16 | 0/15 | broad suite predates the shipped 14px profile; 14px pilot: 8/8 exact, 0 inventions, 11/15 hex: pilot & quality |
glm-5.3-flash (@cf/zai-org/glm-5.3-flash, unsupported) |
Spleen 5×8, 152 cols (default fallback, nothing shipped) | 36/100 | 57/98 | 6/18 | 0/16 | 0/15 | 5×8 is illegible to GLM (0/15 hex); 14px pilot: 10/15 hex, all misses single-glyph confabs, guards 0/16: pilot & quality |
deepseek-v4.1-flash-1017 (@cf/deepseek-ai/deepseek-v4.1-flash-1017, unsupported) |
JetBrains Mono 14px, 84 cols (pilot, nothing shipped) | 100/100 | 98/98 | 18/18 | 0/16 | 0/15 | 5×8 is illegible to DeepSeek V4.1 (0/15 hex); 14px pilot: 100/100 arith, 98/98 gist, 18/18 state, 0/16 guards, 8/15 hex: pilot & quality |
Offline export of the same deterministic 454,045-character dense record corpus through each complete profile produced:
| model profile | pages | text estimate | image tokens | savings |
|---|---|---|---|---|
| Claude, Spleen 5×8 | 17 | 122,715 | 23,856 | 80.6% |
| Sol, JetBrains Mono 14px | 45 | 122,715 | 65,424 | 46.7% |
The text estimate uses 3.7 characters/token; image tokens use each model's provider formula and actual rendered page dimensions. These figures establish profile cost on this corpus, not a universal workload savings rate. Sol's paid fixtures estimated 42% while reading 7/8 exact with no unsupported inventions.
The runs use different transports and profile generations, not one identical
image geometry. Fable and Opus use Claude; Gemini uses Google AI Studio; Sol
and Grok use Codex Responses; Kimi K3 uses Cloudflare's OpenAI-compatible
transport. All dense hex (N=15) scores are pure-image reads with no factsheet.
Current production profiles include the adjacent bounded factsheet on runtime requests;
historical or pure-image exceptions are identified in the linked evaluation.
These are not cross-model comparisons. Every unlisted model is not run.
| test | model | result | evaluation and receipts |
|---|---|---|---|
| SWE-bench Lite | claude-fable-5 |
pxpipe 10/10; text 10/10; −65% request size | paired pilot |
| SWE-bench Pro | claude-fable-5 |
pxpipe 14/19; text 15/19; −60% request size | paired pilot |
| production-history row localization | google/gemini-3.6-flash |
text 17/30; pxpipe 18/30 | positional retrieval |
| production-history exact row | google/gemini-3.6-flash |
text 3/30; pxpipe 3/30 | positional retrieval |
The SWE-bench runner is Claude Code/Fable-specific; no other model has an ON/OFF run. Gemini's positional-retrieval sweep is directional evidence, not a general Lost-in-the-Middle result.
Measured by rendering this repo’s dense fixture through the real pipeline and pricing pixels at each family’s vision rate. Multiplier = measured chars/vision-token ÷ 4 (prose text baseline). Not a model-quality score.
| family | window | as text (@4 c/tok) | as pxpipe images | density | multiplier |
|---|---|---|---|---|---|
claude-fable-5[1m] (default) |
1M | ~4.0M | ~18.9M | ~18.9 c/vt (exact 28px patches) | ~4.7× |
google/gemini-3.6-flash |
1M | ~4.0M | ~20.1M | ~20.1 c/vt (1,078 tok/page) | ~5.0× |
claude-opus-5 |
1M | ~4.0M | ~18.9M | ~18.9 c/vt (resolves to Fable 5’s geometry) | ~4.7× |
Regenerate: npx tsx scripts/gen-context-chart.ts · chart PNG
docs/assets/context-window-chars.png.
The older GSM8K result is omitted because its training-data contamination can hide image misreads; the linked arithmetic evaluations use novel numbers.
model id ──► render profile ──► wrap/reflow bulk context ──► PNG[] + bounded factsheet
The proxy handles Anthropic Messages, OpenAI Responses and Chat Completions,
and Google generateContent requests. It rewrites eligible bulk into image
blocks and forwards the provider-native request, or bridges Anthropic Messages
to a configured OpenAI-compatible provider. On Anthropic, the static prefix and
prompt-cache boundary are preserved. Model-specific profiles control geometry,
factsheets, history retention, and profitability, so sparse prose stays text.
Events log to ~/.pxpipe/events.jsonl.
import { renderTextToImages, transformAnthropicMessages } from "pxpipe-proxy";

const { pages } = await renderTextToImages(toolResultText);     // pages[i].png: Uint8Array
const { body, applied, info } = await transformAnthropicMessages({
  body: requestBytes,
  model: "claude-fable-5",
});
options.keepSharp(block) pins blocks as text; options.emitRecoverable
returns the originals of imaged blocks. Pure-JS runtime (Node and
edge/Workers); @napi-rs/canvas is build-time only. Full API:
src/core/index.ts.
Offline stats (no proxy): pxpipe stats
The live dashboard shows savings while the proxy is running. To read the same event log after the fact — with no server up — summarize it straight from disk:
pxpipe stats                   # human report from ~/.pxpipe/events.jsonl
pxpipe stats --json            # same aggregate as machine-readable JSON
pxpipe stats --file /path/to/events.jsonl
Alongside request counts, compression ratios, latency percentiles, and
cache-hit rates, the report prints a measured savings headline —
count_tokens of the original body versus real usage, over probe-measured rows
only (unmeasured requests are excluded, never counted as zero). This is a
raw-token figure (cache reads at face value, not cost-weighted), so it is
deliberately a different quantity from the dashboard's cost-weighted saved %.
Point it at a non-default log with --file, or set PXPIPE_LOG.
Exit codes: 0 report printed, 1 events file not found, 2 file present but
no valid events. pxpipe stats --help prints usage.
pnpm install && pnpm test
pnpm run build                # regenerates dist/
Windows is community-supported: primary development targets macOS/Linux, and Windows-specific fixes rely on contributor PRs (thanks @makoribrian).
Is the headline end-to-end, or only on the requests you touched?
End-to-end, the whole bill. Most compression tools report savings only on the input slice they touched, which flatters the number. The end-to-end denominator is every production request: the small ones pxpipe correctly left untouched, all cache writes and reads, and all output tokens (which the proxy never compresses). On a 13,709-request snapshot that was 59% ($100 → ~$41); a later 8,904-compressed-request trace measured ~70%. Compressed-only runs higher (~72–74%) and is quoted separately, never as the headline. The exact figure is workload-dependent — reproduce it on your own log.
How is the math measured?
Both sides of the same request, at the same moment. For every /v1/messages
POST the proxy fires a free count_tokens probe on the original uncompressed
body (the counterfactual) in parallel with the real forward, and reads
Anthropic's actually-billed usage block off the response. Both land in the
same row of ~/.pxpipe/events.jsonl, so there is no turn-count or
run-to-run confound. Dollar conversion uses Fable 5 list ratios: input ×1.0,
cache write ×1.25, cache read ×0.1, output ×5. Cache pricing is applied
identically to both sides, so the caching discount cancels and cannot be
double-counted as "savings". Re-derive it yourself from the events log: the
formula and field names are documented in src/core/baseline.ts.
What does it actually compress?
Three kinds of input blocks, each behind a profitability gate:
- large
tool_resultbodies (file reads, command output, logs) above ~6k chars of token-dense content - older collapsed history: turns behind the live tail get re-rendered as image pages, recent turns always stay text
- the static cacheable system prompt + tool docs slab; appended non-cacheable system blocks stay live text so host custom instructions keep system-level salience
Everything else passes through byte-identical: your messages, recent turns, the model's output (it is the response, the proxy never touches it), sparse prose, and anything too small to win. Model defaults and detailed results are listed under model support and benchmarks.
Has it ever failed for real, outside the benchmarks?
Yes, once in weeks of daily use: the model recalled a person's name from imaged chat history and got it confidently wrong. No error, just a plausible wrong name. That is the documented failure mode: exact strings in imaged content are not byte-safe. Coding sessions tolerate this because the agent re-reads files before editing; pure chat recall has no such check. This failure mode is measured, not anecdotal: the legibility audit quantifies exact-string recall off rendered pages (blind reads top out at 63% on dense identifiers, with every miss predicted by a glyph-confusability matrix) and documents the shipped mitigations — page geometry clamped to the API's resample cap so billed pixels actually reach the vision encoder, and selected identifiers (SHAs, numbers) riding alongside as text.
Why are misses silent confabulations instead of read errors?
Because model vision is not OCR: the image becomes patch embeddings, never discrete characters, so there is no per-glyph confidence to fail loudly on. When pixels underdetermine a glyph, the language prior fills the gap with something plausible. Mechanism and receipts: docs/NOT-OCR.md.
Didn't DeepSeek-OCR show this doesn't hold up in practice?
No: it proved the channel works, using an encoder/decoder pair trained for
the job. The skepticism dates from October 2025, when no stock production
model could read dense renders; that changed with June 2026 claude-fable-5 (13/15
pure-image verbatim hex vs 0/15 on prior Opus) and Gemini (14/15 on Gemini 3.6–3.8
Flash, 15/15 on Gemini 4 Argon pure-image), even as later Claude 5.5
and Fable 5.1 releases regressed to 2/15–6/15. Timeline and per-model
numbers: docs/NOT-OCR.md.
Why does the README read like an AI wrote it?
Because one did. Most of this repo's commits — the code and the docs — were authored by Opus/Fable agent sessions running behind pxpipe itself, reading their own collapsed history as image pages while they worked.
- PNG encoding adds latency to large requests before they leave.
- ASCII/Latin-1 well tested; CJK works but conservatively.
Current as of October 2026. Exact recall at 5×8 density is bottlenecked by the
model's vision encoder, not just font tweaks: repainting K reduced Fable 5's
H/K confusion from 47.2% to 18.7% (FINDINGS.md, 2026-07-19),
while later Claude releases (claude-fable-5-1 at 6/15, claude-opus-5-5 at
3/15, claude-sonnet-5-5 at 2/15) regressed relative to June 2026
claude-fable-5 (13/15). Conversely, Gemini 4 (gemini-4-argon) cleared the
5×8 resolution tripwire at 15/15 pure-image dense hex, 100/100
pure-image arithmetic, and 93% / 90% pure-image hex/number recall on the 6-document TokenSave corpus; we tested removing the factsheet on Gemini 4 and kept it after observing single-pixel 0↔8 substitutions in 22-char req_ IDs (FINDINGS.md, 2026-10-25 entry).
Effective-context benefits remain unproven. The production-history results above are directional evidence, not a general context-window or long-task accuracy claim.
Third-party projects listed here are not maintained or supported by pxpipe.
- pxpipe-windows — Windows support for
pxpipe mitm(node-forge CA in place of openssl, Task Scheduler autostart). - OmniGlyph — A community-maintained project derived from pxpipe and used by OmniRoute.
- pxpipe-go — A Go port of pxpipe's core with a CLI wrapper, standalone proxy, and embeddable library for Anthropic Messages and OpenAI Chat/Responses.
MIT.